Document libraries, semantic retrieval and source-grounded chat in a shared knowledge workspace.
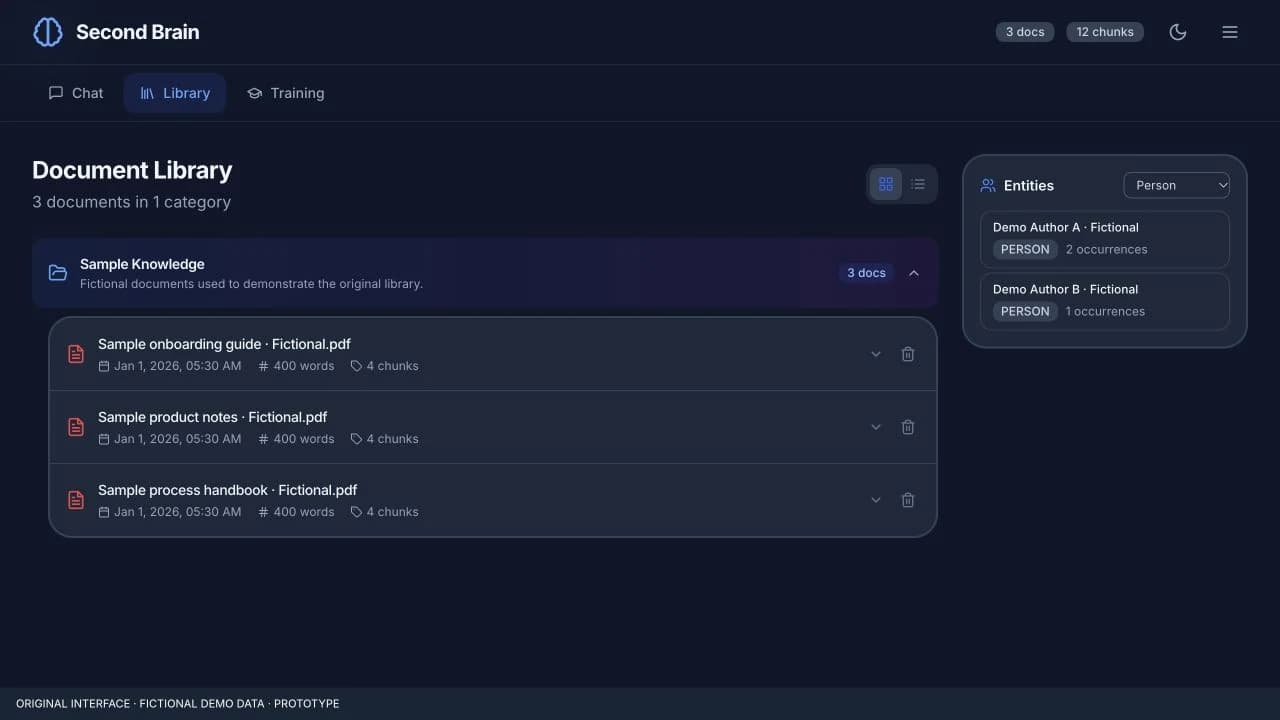 Original prototype interface · local fictional demo data.
The system at a glance.
- System
- Document intelligence / RAG
- Focus
- AI
- Status
- Prototype
The challenge.
Make a growing document collection useful beyond filenames and folders.
How the parts connect.
Document ingestion and indexing connect a library, retrieval layer and conversational interface.
What it handles.
Document library
Organise document metadata in category and list views.
Semantic retrieval
A retrieval layer connects natural-language questions to document passages.
Grounded chat
The chat workspace offers conversation history and response-mode controls.
Source context
Document references remain part of the retrieval and chat interface.
Entity views
Explore extracted entity types alongside the document library.
Document categories
Group related material without losing access to individual documents.
OCR ingestion
The ingestion pipeline handles scanned documents and image text alongside digital files.
Knowledge graph
Extracted entities connect documents through a graph model used by the retrieval layer.
A workspace for each role.
Switch between categories, document lists and chat while retaining the same knowledge context.
The work, end to end.
- 01Document
- 02Indexed passages
- 03Semantic retrieval
- 01Question
- 02Relevant sources
- 03Response
- 01Library
- 02Categories and entities
- 03Document context
Engineering focus.
React / TypeScript / Express / MongoDB / Redis / OpenAI / Document retrieval
Project infrastructure details are not published.
Inside the interface.
Original interface · Demo data
What we delivered.
An implemented document intelligence prototype. Public screenshots use fictional local fixtures.